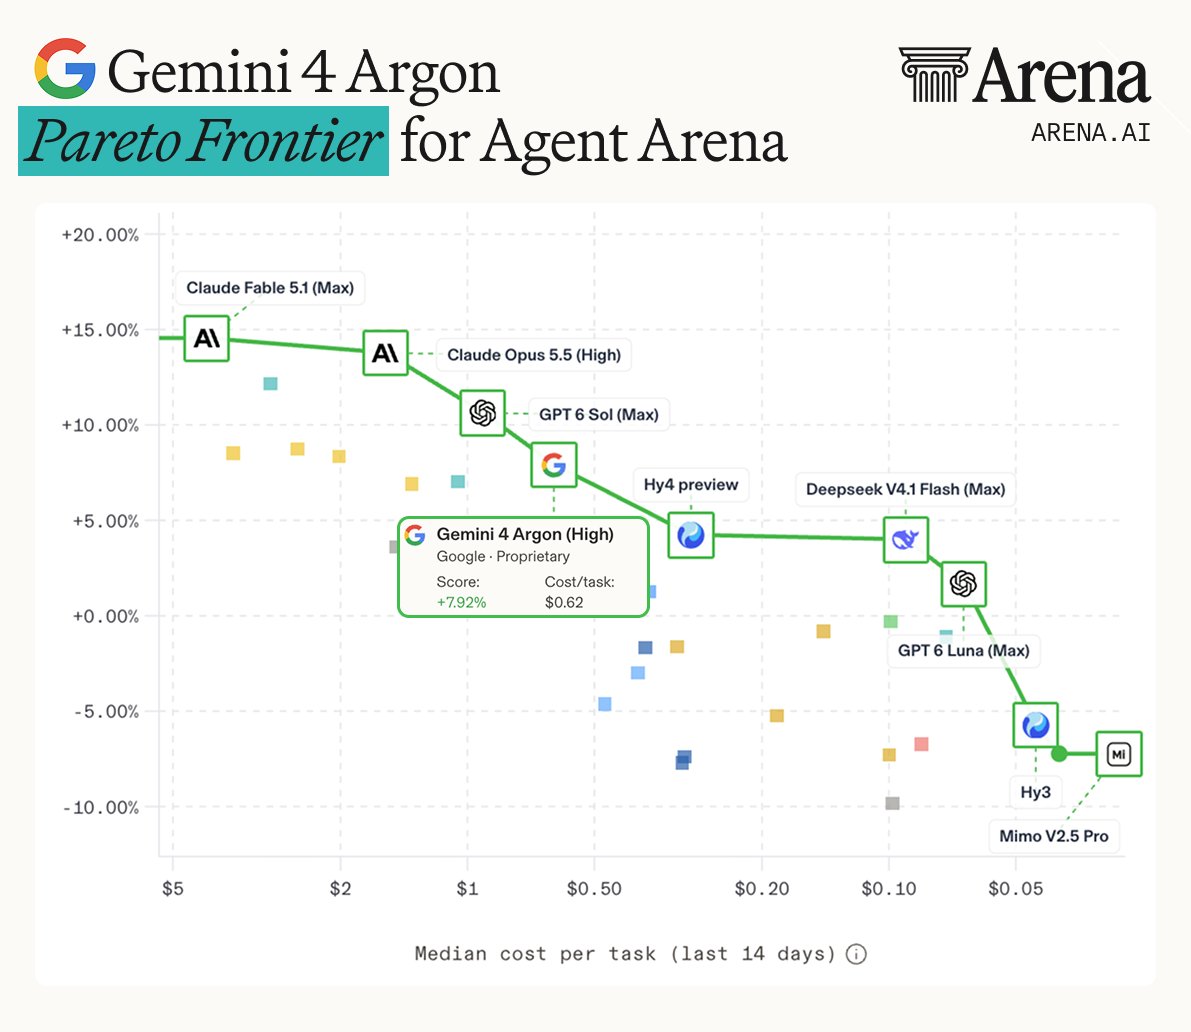
Gemini 4 Argon ranks eighth overall but first at responding to user corrections in Arena’s new results from real agent sessions. At high reasoning, it places ahead of Gemini 3.8 Flash in nineteenth, with a median task cost of $0.62 versus Flash’s $0.58.
Unlike Arena’s head-to-head chat votes, Agent Arena randomly assigns models to handle users’ tasks, then measures feedback and tool behavior. Its steerability signal checks whether a user accepts the agent’s fix after correcting it. Argon also ranks second on explicit user-confirmed success.
The overall score combines those signals with praise versus complaints, recovery from failed commands and attempts to call nonexistent tools. Argon’s +7.92% net improvement is an estimated gain over Arena’s baseline, not the percentage of jobs it completes. Claude Fable 5.1 at maximum effort leads the overall ranking.
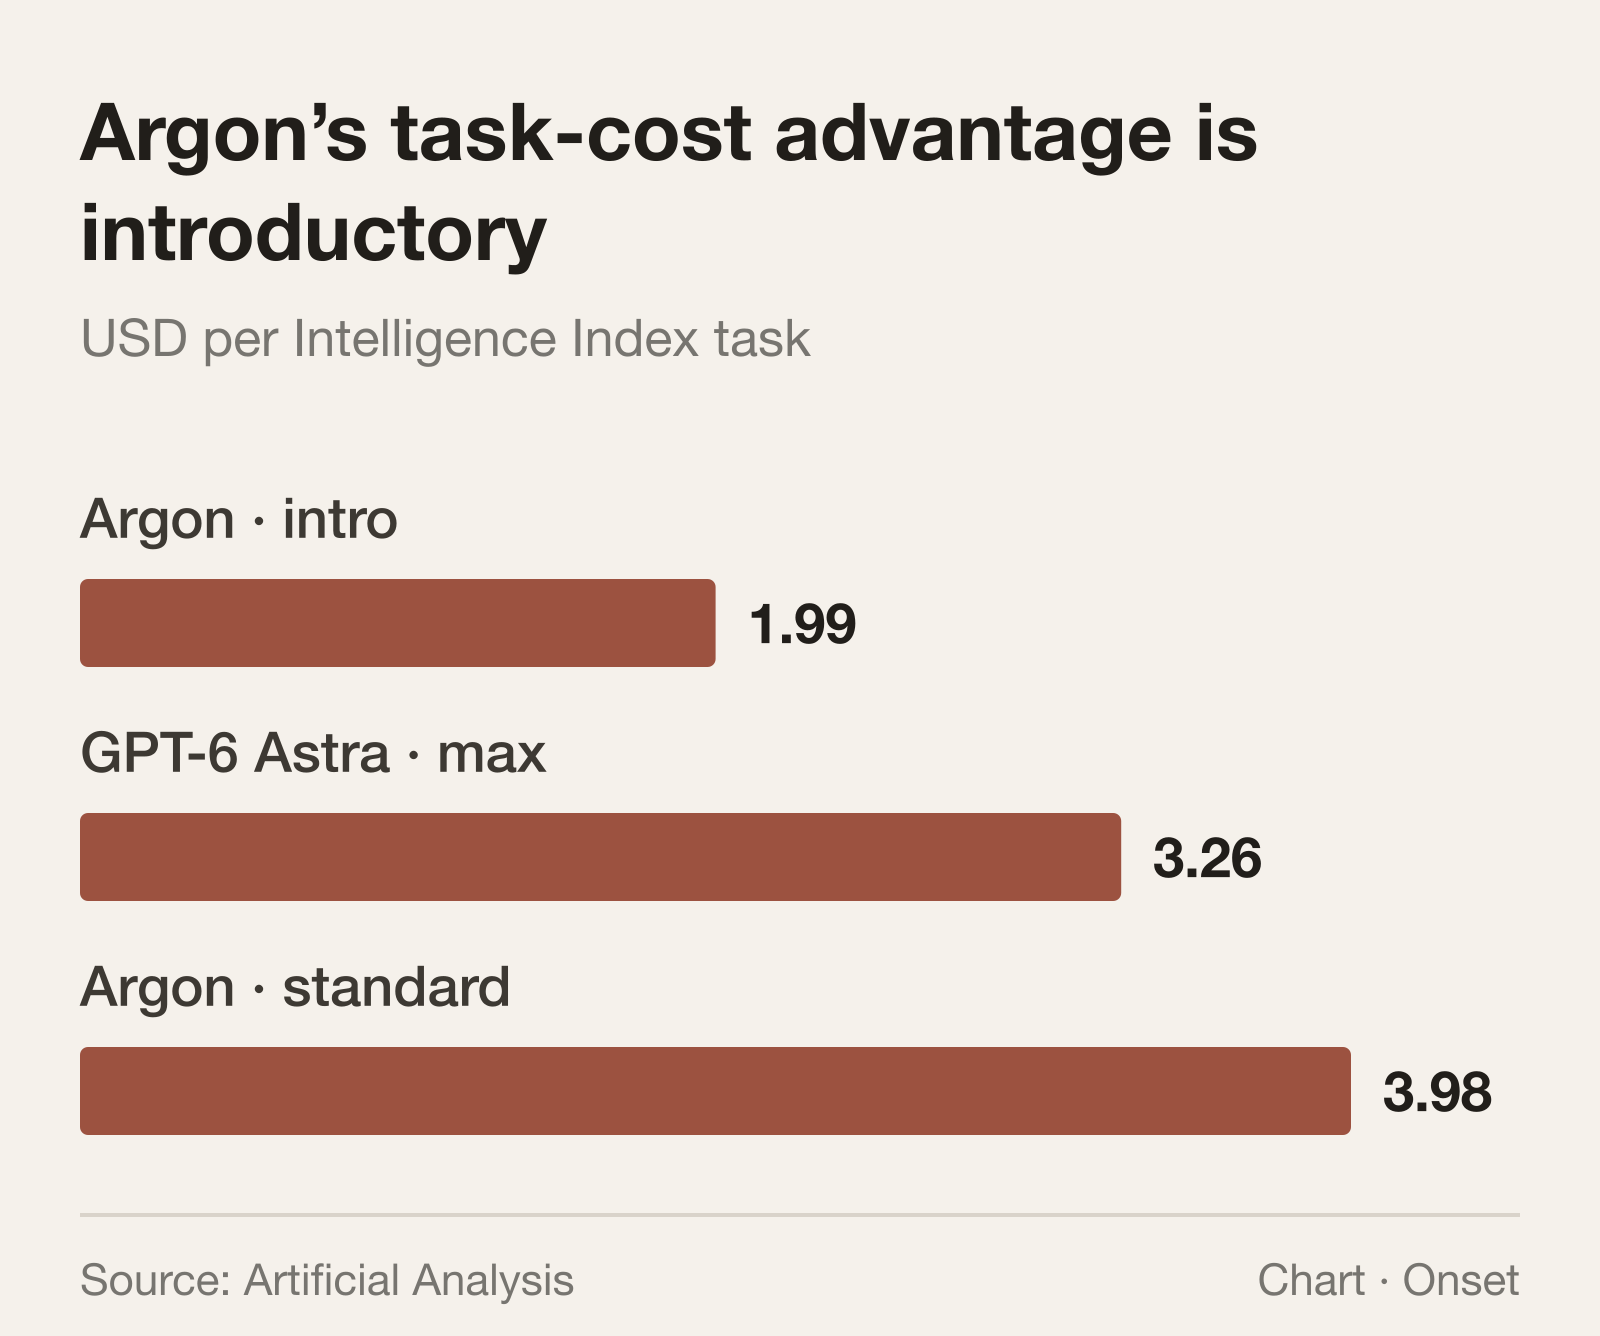
The result is preliminary: Argon has 3,417 sessions, and its overall score carries a 95% confidence interval of ±3.24 percentage points. Its $0.62 median uses Google’s introductory $2/$10 input/output rates per million tokens, so it is not a permanent-price estimate.
The useful early signal is about collaboration: Argon looks particularly good at getting back on track when a person intervenes. That is different from demonstrating reliable, unattended work.